OCR-Based PDF-to-Word Form Population
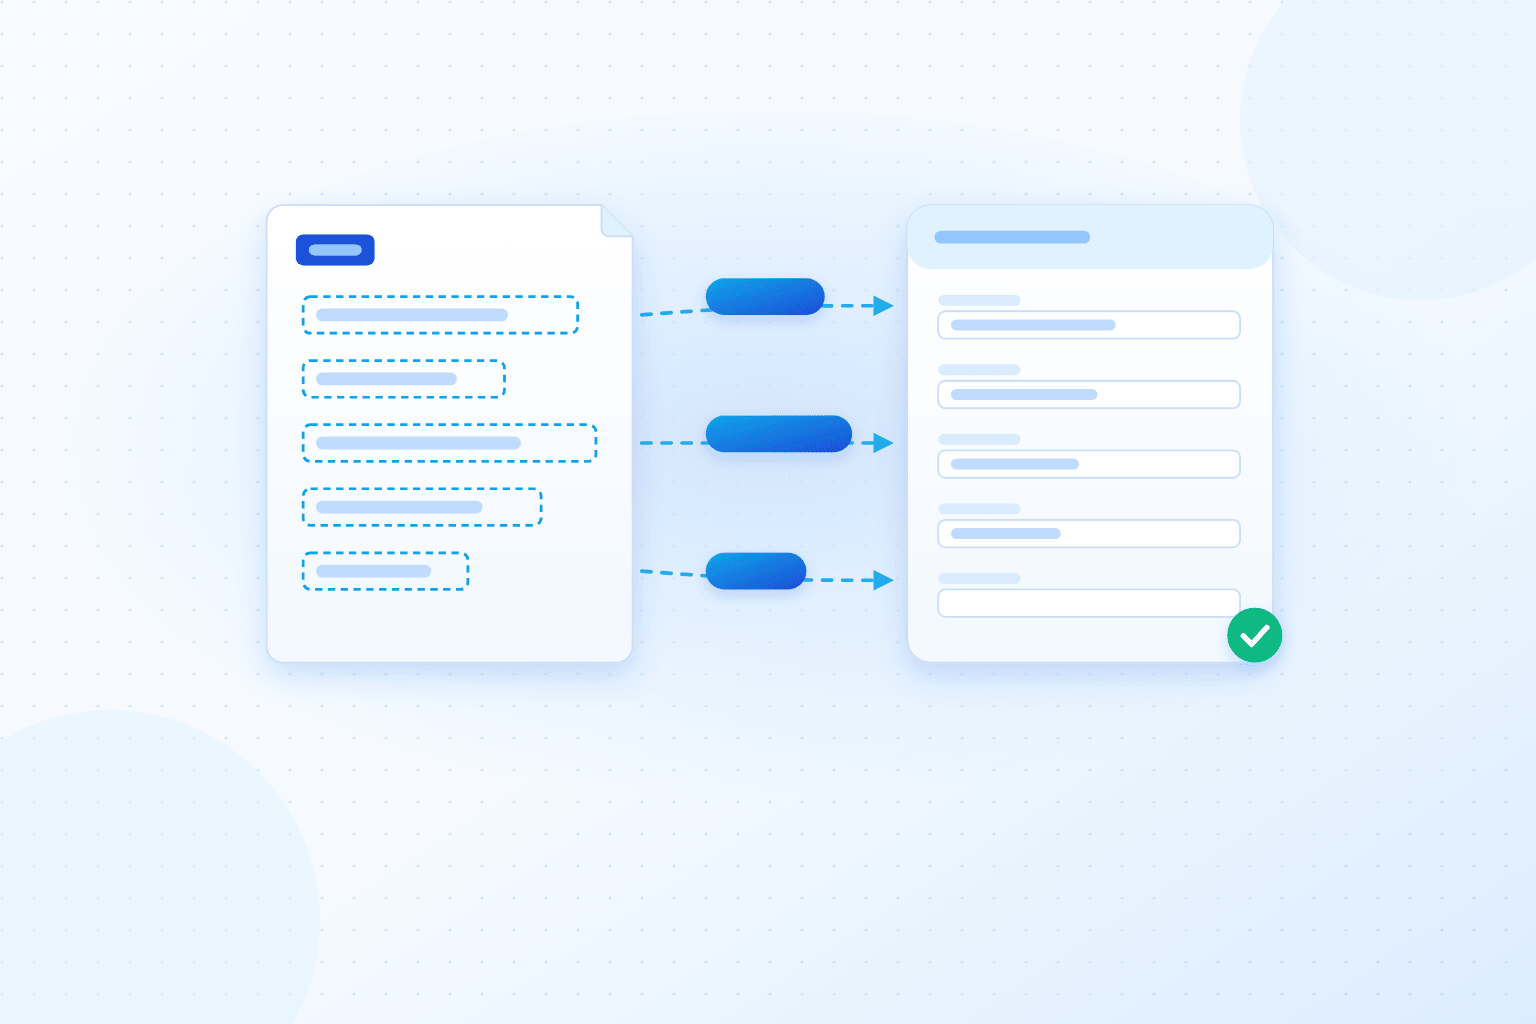
Reads PDF packages with OCR and fills the matching fields in Word form templates, replacing manual transcription.
Problem / Challenge
Fields on Word form templates had to be typed in by hand from the matching PDF packages.
Solution
A desktop tool, packaged with PyInstaller and given a tkinter interface, renders PDF pages with PyMuPDF and runs Tesseract OCR. It maps the extracted text into the Word template's fields and saves the completed forms.
How it works
- Add PDF packages and Word templates
- Render PDF pages
- OCR the text
- Map text to Word fields
- Save completed forms
About this project
This project is from the professional portfolio of Muhammad Umer, Founder & CEO of EaseWorkflow. It is shown as an example of his automation work, not as an EaseWorkflow client engagement. Client and identifying details have been removed.
Results / Outcome
- Designed to cut manual transcription from PDFs into Word forms.